A: Experiment cockpit vs B: Fast winner board
Shipwright
An A/B testing platform where AI and humans compare working implementations before merge.
AI + human A/B testing
Build two. See both. Decide together—before merge.
Shipwright creates or accepts competing implementations, runs them in the browser, and captures Playwright evidence. Model judges score each option while people review, annotate, and vote against the same proof.
Dissent, uncertainty, and implementation risk stay visible. The output is a promote-or-hold decision and a bounded handoff for the winning implementation—not an automatic merge.
Playwright and runtime proof ground the comparison in working UI.
Independent rationales stay attributable instead of collapsing into one opaque score.
2 dissent and risk notes remain visible beside the vote.
Variant A clears the A/B threshold by 2.4 weighted points. Hold promotion because visual evidence is missing. The A/B decision can be discussed, but promotion needs a rendered screenshot before build work starts.
The selected implementation becomes a bounded brief. Governed execution and release receipts stay downstream.
Product model
Collaborative A/B Decision Loop
Shipwright is the A/B testing platform. It makes competing implementations comparable, combines model judgment with human review, and decides what earns a bounded handoff before merge.
-
1
Create
Generate or accept competing implementations for the same brief.
-
2
Capture
Run every option in a browser and collect Playwright proof.
-
3
Judge
Ask multiple models to score the implementations and explain why.
-
4
Review
Put human votes, annotations, dissent, and risks beside model evidence.
-
5
Decide
Promote a winner only when the evidence clears the gate; otherwise hold.
-
6
Handoff
Turn the selected implementation into a bounded packet before merge.
Current comparison
Variant A / Experiment cockpit leads with high confidence.
The evidence packet keeps model rationales, human votes, Playwright captures, 2 dissent and risk notes, and the promotion threshold together.
Bounded execution after decision
Execution lane: Observe
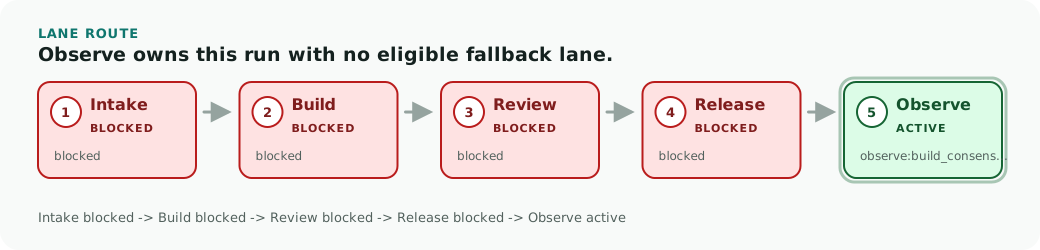
Governed lanes execute only the selected, bounded handoff. Release receipts prove what eventually shipped. Observe owns this run; 0 fallback lanes remain eligible and 4 lanes are blocked or off.
Active 1
Eligible 0
Blocked 4
Off 0
Route map
Observe owns this run with no eligible fallback lane.
Intake blocked -> Build blocked -> Review blocked -> Release blocked -> Observe active
Step 5/5
Fallback None
Blocked 4
Off 0
Work starts here for this run.
No fallback lane is currently eligible.
4 lanes need signal or repair before routing.
0 lanes are disabled by configuration.
-
1
Intake blocked
No task is queued in this lane for the current run.
-
2
Build blocked
No task is queued in this lane for the current run.
-
3
Review blocked
No task is queued in this lane for the current run.
-
4
Release blocked
No task is queued in this lane for the current run.
-
5
Observe active
Pre-orchestration report context builds A/B consensus work orders before the worker prompt is selected.
blocked
Intake
Find product signal and shape the next work.
- Next action
- No task queued
- Why now
- No task is queued in this lane for the current run.
- Priority
- none
Evidence
- action_status: missing
- candidate_priority: none
- selected: false
blocked
Build
Edit code behind a bounded implementation brief.
- Next action
- No task queued
- Why now
- No task is queued in this lane for the current run.
- Priority
- none
Evidence
- action_status: missing
- candidate_priority: none
- selected: false
blocked
Review
Resolve feedback, risk, and verification gaps.
- Next action
- No task queued
- Why now
- No task is queued in this lane for the current run.
- Priority
- none
Evidence
- action_status: missing
- candidate_priority: none
- selected: false
blocked
Release
Publish or promote already verified work.
- Next action
- No task queued
- Why now
- No task is queued in this lane for the current run.
- Priority
- none
Evidence
- action_status: missing
- candidate_priority: none
- selected: false
active
Observe
Measure the result and improve the next loop.
- Next action
- observe:build_consensus_context
- Why now
- Pre-orchestration report context builds A/B consensus work orders before the worker prompt is selected.
- Priority
- none
Evidence
- action_status: missing
- candidate_priority: none
- selected: true
Released capability · Surface Grill v0
External Surface Evidence, pinned to the pixels under review.
Import one existing A/B PNG, annotate exact normalized coordinates, and hand engineering a digest-bound revision packet instead of a loose screenshot thread.
shipwright grill --surface-file variant-b.png --source-digest sha256:<digest>
- The imported image is copied into an immutable, SHA-256-bound session.
- Must-fixes, accepted feedback, and dissent stay attached to spatial pins.
- Every change emits immutable JSON and Markdown packets; source editing remains outside v0.
Released capability · Proof Story v0
Turn a verified change into a short release story without letting the renderer outrun the proof.
Compile an approved claim set, a published commit receipt, a deployed HTTPS receipt, and a fresh production capture into a 15-second browser story, poster, share copy, release-note draft, and machine-readable provenance manifest.
Open the first Proof Story →shipwright proof-story --brief proof-story.json --output-dir site/proof-story
- Every visible claim names the exact receipt or capture that supports it.
- Stale captures, wrong origins, missing proof, and credential-shaped story text fail closed.
- No model, music, telemetry, simulated interaction, provider, or automatic posting is involved.
Experiment cockpit
observe:build_consensus_context
Scored model votes across judge runs.
4 blockers recorded in this build snapshot.
Evidence Bundle
Artifact manifest is missing 11 required evidence files.
Bundle incomplete
Missing 11
Health missing
Required 34
Ready 4
Attention 5
GitHub Adoption
Reusable Project Setup
Installer output, repo settings, provider readiness, and website publishing are tracked as one onboarding path.
shipwright github-setup --repo matthoffner/shipwright --workflow .github/workflows/shipwright.yml --schedule-mode dry_run --dispatch-dry-run --publish-site false
gh workflow run .github/workflows/shipwright.yml -f mode=dry_run -f publish_site=false
No Shipwright adoption check has been recorded for this report.
Setup helper has not been recorded for this repo yet.
No Shipwright workflow gate status has been recorded.
No Shipwright adoption smoke status has been recorded.
No Shipwright doctor status has been recorded for this report.
OPENROUTER_API_KEY is not set; Codex provider setup was skipped.
Canonical Vercel production artifact is deployed from e80ed23 on main.
Evidence Index
Run Evidence
missing12 evidence components missing; Observe owns this run; 0 fallback lanes remain eligible and 4 lanes are blocked or off.
Next Actions
- Shipwright Site: needs more signal
- Onboarding Flow Experiment: needs more signal
- Pricing Page Experiment: needs more signal
- Product history Focused Section Size: fail - Largest changelog section has 225 entries; DevBox-style sections stay small and outcome-specific.
- Run shipwright doctor before enabling scheduled autonomous runs.
- Run shipwright ci-run before enabling scheduled writes.
Lane Board
readyObserve owns this run; 0 fallback lanes remain eligible and 4 lanes are blocked or off.
Evidence
- outcome: dry_run
- mode: dry_run
- selected_lane: observe
- selected_task: observe:build_consensus_context
Next Actions
- Execute observe:build_consensus_context in the Observe lane.
- Clear blocker for intake: No task is queued in this lane for the current run.
- Clear blocker for build: No task is queued in this lane for the current run.
Current State
attentionEvidence-Bound Release Stories is the latest product outcome; 0 work orders ready, 4 blocked targets across 4 failing checks.
Evidence
- ready_work_orders: 0
- blocked: 4
- blocking_checks: 4
Next Actions
- Shipwright Site: needs more signal
- Onboarding Flow Experiment: needs more signal
- Pricing Page Experiment: needs more signal
A/B Consensus Queue
readyShipwright Site is the first A/B consensus blocker; clear the evidence gaps before promoting Variant A.
Evidence
- work_orders: 3
- ship: 0
- watch: 0
- blocked: 3
Next Actions
- Complete the primary unblock action for Shipwright Site: Run surface capture after the target runtime renders all expected signals.
- Regenerate the report and confirm the item leaves blocked status or records a narrower blocker.
Doctor
missingNo Shipwright doctor status has been recorded for this report.
Evidence
- metrics/doctor-status.json missing
Next Actions
- Run shipwright doctor before enabling scheduled autonomous runs.
Adoption
missingNo Shipwright adoption check has been recorded for this report.
Evidence
- metrics/adoption-status.json missing
Next Actions
- Run shipwright ci-run before enabling scheduled writes.
Adoption Smoke
missingNo Shipwright adoption smoke status has been recorded.
Evidence
- metrics/adoption-smoke-status.json missing
Next Actions
- Run shipwright adoption-smoke before enabling external project schedules.
Project Dependencies
missingNo project dependency install status has been recorded.
Evidence
- metrics/project-dependency-status.json missing
Next Actions
- Run shipwright install-project-dependencies before verification.
Browser Install
missingNo Playwright browser install status has been recorded.
Evidence
- metrics/browser-install-status.json missing
Next Actions
- Run shipwright install-browser before surface capture steps.
Workflow Gate
missingNo Shipwright workflow gate status has been recorded.
Evidence
- metrics/workflow-gate-status.json missing
Next Actions
- Run shipwright workflow-gate before the long CI pipeline starts.
CI Run
missingCI run has not been recorded for this report.
Evidence
- metrics/ci-run-status.json missing
Next Actions
- Run shipwright ci-run in CI.
CI Preflight
missingCI preflight has not been recorded for this report.
Evidence
- metrics/ci-preflight-status.json missing
Next Actions
- Run shipwright ci-preflight in CI.
CI Work Cycle
missingCI work cycle has not been recorded for this report.
Evidence
- metrics/ci-work-cycle-status.json missing
Next Actions
- Run shipwright ci-work-cycle in CI.
Safety
missingNo Shipwright safety check has been recorded for this report.
Evidence
- safety-status.json missing
Next Actions
- Run shipwright safety-check before orchestration in GitHub Actions.
Verification
attentionNo verification status has been recorded for this report.
Evidence
- metrics/verification-status.json missing
Next Actions
- Run shipwright verify after autonomous worker changes to capture verification evidence.
Autonomy Readiness
missingNo Shipwright autonomy readiness status has been recorded for this report.
Evidence
- metrics/autonomy-readiness-status.json missing
Next Actions
- Run shipwright ci-work-cycle before enabling autonomous or YOLO writes.
Deployment
readyCanonical Vercel production artifact is deployed from e80ed23 on main.
Evidence
- provider: vercel
- state: deployed
- blocker: none
- VERCEL_TOKEN: missing
CI Finalize
missingCI finalize has not been recorded for this report.
Evidence
- metrics/ci-finalize-status.json missing
Next Actions
- Run shipwright ci-finalize in CI.
Git Publish
readyRelease source e80ed23 is published on origin/main and bound to this Vercel production artifact.
Evidence
- commit: e80ed238331eafc832b280945d9e9190863786d4
- identity_source: vercel
- checkout_commit: missing
- remote_ref: missing
Codex Provider
attentionOPENROUTER_API_KEY is not set; Codex provider setup was skipped.
Evidence
- provider: openrouter
- model: openai/gpt-5.1-codex-mini
- OPENROUTER_API_KEY: missing
Next Actions
- Add OPENROUTER_API_KEY as a GitHub Actions secret before non-dry-run writes.
Codex Worker
attentionNo Codex worker run has been recorded for this report.
Evidence
- codex-worker-status.json missing
Next Actions
- Run Shipwright Dogfood in non-dry-run mode to capture worker execution evidence.
Worker Contract
attentionNo Codex worker contract trace has been recorded for this report.
Evidence
- commands: 0
- first edit command index: -1
Next Actions
- Run Shipwright Dogfood in non-dry-run mode to capture worker contract evidence.
Build Evidence Snapshot
Evidence-Bound Release Stories is the latest product outcome; 0 work orders ready, 4 blocked targets across 4 failing checks.
Journal-independent build snapshot assembled from product history, consensus, runtime, credential, and screenshot evidence.
A/B accepted0/3
Work orders0
Blocked targets4
Failing checks4
Deploy blocked0
Rendered targets1/3
Captured surfaces0/0
Build Snapshot Details Work orders, blockers, next actions, and evidence sources captured by this build.
Work Orders
Consensus
- Clear blocker: Shipwright Site 40%
Shipwright Site is 40% ready; clear the failing gate before assigning Variant A. - Clear blocker: Onboarding Flow Experiment 40%
Onboarding Flow Experiment is 40% ready; clear the failing gate before assigning Variant A. - Clear blocker: Pricing Page Experiment 40%
Pricing Page Experiment is 40% ready; clear the failing gate before assigning Variant B.
Ready
Signals
- Shipwright A/B Lab: rendered 3/3
- 0/3 A/B consensus decisions accepted
- Shipwright Site deploy: deployed to https://shipwright-seven-murex.vercel.app
Blocked
Blockers
- Shipwright Site: needs more signal
- Onboarding Flow Experiment: needs more signal
- Pricing Page Experiment: needs more signal
- Product history Focused Section Size: fail - Largest changelog section has 225 entries; DevBox-style sections stay small and outcome-specific.
Next
Actions
- Split oversized sections into narrower dated outcomes before the website treats product history as healthy.
- Run `shipwright capture-surfaces` after report generation and publish site/surface-captures.json with a captured screenshot.
- Add lightweight page events once Shipwright has real recurring users.
- Compare first-viewport comprehension after each generated site change.
- Capture real usage events after the first UI slice ships.
- Keep validating the generated website before using it as the baseline for other experiment subjects.
Evidence
Sources
- Derived from CHANGELOG.md product history, not raw journal prose.
- Uses target runtime, credential, screenshot, dogfood plan, and A/B consensus artifacts.
- Uses deployment status evidence so the website cannot silently drift behind CI.
- Run journal remains audit evidence only.
UI Consensus
Variant A: Experiment cockpit
Should Shipwright lead with a toggleable experiment cockpit or a fast winner board?
Variant A wins because Shipwright is becoming an autonomous A/B platform: generate two UI versions, capture them with Playwright, ask multiple LLMs to judge, let humans vote, then hand the winner to an agent.
Consensus handoff
Render a first-class Variant A / Variant B toggle on the website.
Score
9.1 / 6.7Margin 2.4; high confidence; threshold 1.5
Judges
43 selected the winning variant.
Experiment subjects
4Shipwright keeps built-in UI subjects in the same judge-and-vote comparison set.
Variant Toggle The A/B presentation candidates Shipwright can hand to a worker.
Variant Toggle
Experiment cockpit
Lead with a toggleable A/B workspace: Variant A, Variant B, Playwright evidence, model-judge scorecards, and human vote state.
Strengths
- Makes each autonomous UI run inspectable without reading raw logs.
- Turns the website into a product control surface for A/B decisions.
- Gives model judges and humans the same evidence packet.
Risks
- Needs strong hierarchy so the cockpit does not feel like raw CI output.
- Needs real Playwright captures for each generated variant before claims are trusted.
Fast winner board
Lead with the winning variant, summarized rationale, and one next action before showing the deeper judge evidence.
Strengths
- Lets a busy operator see what won immediately.
- Keeps the first viewport lighter for first-time readers.
Risks
- Can hide dissent and weak evidence behind a premature recommendation.
- Makes it harder for humans to audit why the losing variant lost.
Consensus Cockpit Target tabs, evidence, and implementation handoffs.
UI consensus target summary
One-card-per-target view of the A/B winner, vote confidence, runtime proof, screenshot capture, and first worker action.
Shipwright Site
Variant A clears the A/B threshold by 2.4 weighted points.
- Votes
- 3/4 majority, 1 dissent
- Runtime
- rendered 3/3
- Capture
- missing
- First Action
- Promote Variant A: Experiment cockpit as the default website layout.
Onboarding Flow Experiment
Variant A clears the A/B threshold by 1.2 weighted points.
- Votes
- 3/4 majority, 1 dissent
- Runtime
- not configured 0/3
- Capture
- missing
- First Action
- Keep this subject in the default experiment path.
Pricing Page Experiment
The margin is 0.9, below the 1 point threshold, so more signal is required.
- Votes
- 3/4 majority, 1 dissent
- Runtime
- not configured 0/3
- Capture
- missing
- First Action
- Keep this subject in the default experiment path.
Shipwright Site
Variant A: Experiment cockpit
Variant A clears the A/B threshold by 2.4 weighted points.
Readiness
Shipwright A/B Lab rendered 3/3 expected signals and can be used as consensus evidence.
Signals
- credential: not required
- runtime: rendered
- start attempt: not attempted
- matched signals: 3/3
Next Actions
- Keep this subject in the default experiment path.
- Use this rendered runtime as the baseline for the next UI consensus comparison.
Surface Snapshot
Shipwright
Variant A: Experiment cockpit winner
Lead with a toggleable A/B workspace: Variant A, Variant B, Playwright evidence, model-judge scorecards, and human vote state.
Risk: Needs strong hierarchy so the cockpit does not feel like raw CI output.
Variant B: Fast winner board
Lead with the winning variant, summarized rationale, and one next action before showing the deeper judge evidence.
Risk: Can hide dissent and weak evidence behind a premature recommendation.
LLM Judges
- GPT-5.1 Judge chose Variant A at 9/10: The cockpit keeps variants, evidence, model reasoning, and the worker handoff in one decision packet.
- Claude Sonnet Judge chose Variant A at 8/10: A is more honest about uncertainty because it shows the loser, dissent, and evidence gaps before shipping.
- Gemini Judge chose Variant B at 7/10: B is easier to scan, but it needs the cockpit below the fold to keep the decision trustworthy.
- Human Panel chose Variant A at 8/10: People need the toggle and vote record before trusting an autonomous winner.
LLM Judge Matrix
Consensus Response Packet
Should Shipwright lead with a toggleable experiment cockpit or a fast winner board?
3/4 judges selected Variant A. 1 dissenting judge kept Variant B risk visible.
Evidence Checklist
- Decision status: needs_more_signal
- Playwright evidence: missing
- Runtime evidence: rendered
- Strongest criterion: Playwright Evidence +3
- Dissent: Gemini Judge preferred Variant B
| Criterion | Winner | Runner-up | Delta |
|---|---|---|---|
| LLM Judge Agreement | 9 | 7 | +2 |
| Playwright Evidence | 9 | 6 | +3 |
| Human Vote Clarity | 9 | 6 | +3 |
| Agent Handoff | 9 | 8 | +1 |
| Judge | Vote | Alignment | Confidence | Evidence |
|---|---|---|---|---|
| GPT-5.1 Judge | Variant A | majority | 9/10 | role:reasoning model, visual:missing, runtime:rendered, variant:A |
| Claude Sonnet Judge | Variant A | majority | 8/10 | role:product critique, visual:missing, runtime:rendered, variant:A |
| Gemini Judge | Variant B | dissent | 7/10 | role:visual comparison, visual:missing, runtime:rendered, variant:B |
| Human Panel | Variant A | majority | 8/10 | role:group vote, visual:missing, runtime:rendered, variant:A |
Onboarding Flow Experiment
Variant A: Guided checklist
Variant A clears the A/B threshold by 1.2 weighted points.
Readiness
Onboarding Flow Experiment has consensus output but still needs rendered runtime evidence before promotion.
Signals
- credential: not required
- runtime: not configured
- start attempt: not attempted
- matched signals: 0/3
Next Actions
- Keep this subject in the default experiment path.
- Add a runtime URL for Onboarding Flow Experiment so Shipwright can fetch rendered UI evidence.
Surface Snapshot
Untitled surface
npm run check
npm run report
Variant A: Guided checklist winner
Lead onboarding with a concrete sequence of setup, first experiment, judge review, and publish steps.
Risk: Can feel too procedural for experienced users who already know the flow.
Variant B: Autonomous summary
Lead onboarding with what Shipwright already inferred and one high-confidence next action.
Risk: Can hide important setup gaps if the summary is too confident.
LLM Judges
- GPT-5.1 Judge chose Variant A at 9/10: Onboarding Flow Experiment should optimize for the experiment job named by its surface: Built-in onboarding UI variant.
- Claude Sonnet Judge chose Variant A at 8/10: The winning variant creates clearer product intent and a better autonomous handoff.
- Gemini Judge chose Variant B at 7/10: The alternate keeps useful pressure on visual simplicity and first-impression quality.
- Human Panel chose Variant A at 8/10: The group vote favors the direction with the clearest implementation and review path.
LLM Judge Matrix
Consensus Response Packet
Should onboarding lead with a guided checklist or an autonomous summary?
3/4 judges selected Variant A. 1 dissenting judge kept Variant B risk visible.
Evidence Checklist
- Decision status: needs_more_signal
- Playwright evidence: missing
- Runtime evidence: not_configured
- Strongest criterion: Implementation Fit +2
- Dissent: Gemini Judge preferred Variant B
| Criterion | Winner | Runner-up | Delta |
|---|---|---|---|
| Experiment Fit | 9 | 8 | +1 |
| Judgeability | 8 | 7 | +1 |
| Implementation Fit | 9 | 7 | +2 |
| Evidence Quality | 8 | 7 | +1 |
| Judge | Vote | Alignment | Confidence | Evidence |
|---|---|---|---|---|
| GPT-5.1 Judge | Variant A | majority | 9/10 | role:reasoning model, visual:missing, runtime:not_configured, variant:A |
| Claude Sonnet Judge | Variant A | majority | 8/10 | role:product critique, visual:missing, runtime:not_configured, variant:A |
| Gemini Judge | Variant B | dissent | 7/10 | role:visual comparison, visual:missing, runtime:not_configured, variant:B |
| Human Panel | Variant A | majority | 8/10 | role:group vote, visual:missing, runtime:not_configured, variant:A |
Pricing Page Experiment
Variant B: Judge-proof pricing
The margin is 0.9, below the 1 point threshold, so more signal is required.
Readiness
Pricing Page Experiment has consensus output but still needs rendered runtime evidence before promotion.
Signals
- credential: not required
- runtime: not configured
- start attempt: not attempted
- matched signals: 0/3
Next Actions
- Keep this subject in the default experiment path.
- Add a runtime URL for Pricing Page Experiment so Shipwright can fetch rendered UI evidence.
Surface Snapshot
Untitled surface
npm run check
npm run report
Variant A: Simple plan comparison
Lead pricing with straightforward plans, limits, and the first practical upgrade point.
Risk: Underplays the differentiator: autonomous evidence-backed shipping.
Variant B: Judge-proof pricing winner
Lead pricing with proof: experiments run, judges consulted, human votes collected, and winners shipped.
Risk: Requires stronger examples before it beats a simple comparison table.
LLM Judges
- GPT-5.1 Judge chose Variant B at 9/10: Pricing Page Experiment should optimize for the experiment job named by its surface: Built-in pricing UI variant.
- Claude Sonnet Judge chose Variant B at 8/10: The winning variant creates clearer product intent and a better autonomous handoff.
- Gemini Judge chose Variant A at 7/10: The alternate keeps useful pressure on visual simplicity and first-impression quality.
- Human Panel chose Variant B at 8/10: The group vote favors the direction with the clearest implementation and review path.
LLM Judge Matrix
Consensus Response Packet
Should pricing lead with a simple plan comparison or proof from judge outcomes?
3/4 judges selected Variant B. 1 dissenting judge kept Variant A risk visible.
Evidence Checklist
- Decision status: needs_more_signal
- Playwright evidence: missing
- Runtime evidence: not_configured
- Strongest criterion: Evidence Quality +2
- Dissent: Gemini Judge preferred Variant A
| Criterion | Winner | Runner-up | Delta |
|---|---|---|---|
| Experiment Fit | 9 | 8 | +1 |
| Judgeability | 9 | 8 | +1 |
| Implementation Fit | 8 | 9 | -1 |
| Evidence Quality | 9 | 7 | +2 |
| Judge | Vote | Alignment | Confidence | Evidence |
|---|---|---|---|---|
| GPT-5.1 Judge | Variant B | majority | 9/10 | role:reasoning model, visual:missing, runtime:not_configured, variant:B |
| Claude Sonnet Judge | Variant B | majority | 8/10 | role:product critique, visual:missing, runtime:not_configured, variant:B |
| Gemini Judge | Variant A | dissent | 7/10 | role:visual comparison, visual:missing, runtime:not_configured, variant:A |
| Human Panel | Variant B | majority | 8/10 | role:group vote, visual:missing, runtime:not_configured, variant:B |
Scoring Details Rubric, judge votes, and next actions.
A/B Options
Variant A: Experiment cockpit selected
Lead with a toggleable A/B workspace: Variant A, Variant B, Playwright evidence, model-judge scorecards, and human vote state.
Strength: Makes each autonomous UI run inspectable without reading raw logs.
Risk: Needs strong hierarchy so the cockpit does not feel like raw CI output.
Variant B: Fast winner board
Lead with the winning variant, summarized rationale, and one next action before showing the deeper judge evidence.
Strength: Lets a busy operator see what won immediately.
Risk: Can hide dissent and weak evidence behind a premature recommendation.
Weighted Rubric
Variant A 9.1
Experiment cockpit
- LLM Judge Agreement: 9/10, weighted 2.7
- Playwright Evidence: 9/10, weighted 2.3
- Human Vote Clarity: 9/10, weighted 2.3
- Agent Handoff: 9/10, weighted 1.8
Variant B 6.7
Fast winner board
- LLM Judge Agreement: 7/10, weighted 2.1
- Playwright Evidence: 6/10, weighted 1.5
- Human Vote Clarity: 6/10, weighted 1.5
- Agent Handoff: 8/10, weighted 1.6
Decision threshold: Variant A clears the A/B threshold by 2.4 weighted points.
LLM Judge Agreement 30%
Multiple model judges can compare the variants and explain the same winner.
Playwright Evidence 25%
The decision is grounded in rendered UI capture instead of prose alone.
Human Vote Clarity 25%
A group of people can vote, see dissent, and understand how their input affects the result.
Agent Handoff 20%
The selected variant produces a concrete implementation prompt for an autonomous worker.
LLM Judges
GPT-5.1 Judge 9/10
Variant A / reasoning model. The cockpit keeps variants, evidence, model reasoning, and the worker handoff in one decision packet.
Claude Sonnet Judge 8/10
Variant A / product critique. A is more honest about uncertainty because it shows the loser, dissent, and evidence gaps before shipping.
Gemini Judge 7/10
Variant B / visual comparison. B is easier to scan, but it needs the cockpit below the fold to keep the decision trustworthy.
Human Panel 8/10
Variant A / group vote. People need the toggle and vote record before trusting an autonomous winner.
Next Actions
Render a first-class Variant A / Variant B toggle on the website.
Keep model judges, human votes, and Playwright evidence in the same decision packet.
Generate worker prompts from the winning variant only after evidence gates pass.
Judge Runs
No judge-run artifacts have been recorded yet.
A/B Test Consensus
0/3 A/B consensus items are shippable; 3 blocked; 0 need watch.
Operator queue derived from A/B tests, consensus lanes, judge-panel judge matrices, and dogfood readiness.
Clear blocker: Shipwright Site
Shipwright Site is 40% ready; clear the failing gate before assigning Variant A.
Consensus Handoff Packet
Implement the selected Variant A handoff for Shipwright Site in Shipwright.
Metric
- Time-to-action: can a returning operator identify the next useful Shipwright move?
Runtime Proof
- Shipwright A/B Lab rendered evidence is not backed by a captured screenshot yet.
Target Metadata
- Run state: blocked; dogfood blocked; visual missing; promotion needs_more_signal.
- Operator metric: Time-to-action: can a returning operator identify the next useful Shipwright move?
- Consensus: Variant A; 3 majority / 1 dissent; score delta +2.4.
- Current blocker: Screenshot evidence missing: Shipwright A/B Lab rendered evidence is not backed by a captured screenshot yet.
- Next action: Run surface capture after the target runtime renders all expected signals.
- Verification: node dist/cli.js capture-surfaces --registry shipwright.targets.json --site-dir site --output metrics/surface-captures.json
Operator Trust
- Run state: blocked; dogfood blocked; visual missing; promotion needs_more_signal.
Source Boundary
- site/** and metrics/** are generated evidence; make durable changes in source, tests, docs, package metadata, or shipwright.yml.
First Edit
- Start from the renderer or artifact builder that owns the visible report output, then update its focused test.
Worker Edit Recipe
- Real command 1: run the required rg command from the execution prompt.
- Real command 2: inspect one focused renderer or artifact-builder range, 160 lines or less.
- Real command 3: edit the owning source file or its focused test with node --input-type=module -e or perl -0pi; do not run another inspection or apply_patch.
- After the first edit: inspect or update the matching focused test only if needed.
- Change shape: implement or clarify the Variant A Shipwright handoff while preserving the primary metric.
- Verify with npm run build only before finishing; Shipwright CI runs full verification after the worker exits.
Verify Next
- node dist/cli.js capture-surfaces --registry shipwright.targets.json --site-dir site --output metrics/surface-captures.json
Experiment Packet
Allocation
- Variant A: 50% - Experiment cockpit
- Variant B: 50% - Fast winner board
Events
- shipwright_ab_test_exposed
- shipwright_ab_test_primary_signal
- shipwright_ab_test_guardrail_signal
- shipwright_ab_test_decision
Missing Signals
- accepted decision threshold
- captured visual evidence
Proof
- Gate passed: Judge Matrix
- Gate needs work: Decision: watch
- Gate needs work: Promotion: watch
- Gate needs work: Visual: fail
- Shipwright A/B Lab rendered evidence is not backed by a captured screenshot yet.
Acceptance
- Complete the primary unblock action for Shipwright Site: Run surface capture after the target runtime renders all expected signals.
- Regenerate the report and confirm the item leaves blocked status or records a narrower blocker.
Failed Gates
- Decision: watch
- Promotion: watch
- Visual: fail
Verify
- node dist/cli.js capture-surfaces --registry shipwright.targets.json --site-dir site --output metrics/surface-captures.json
- npm run check
- npm run verify:intake
Clear blocker: Onboarding Flow Experiment
Onboarding Flow Experiment is 40% ready; clear the failing gate before assigning Variant A.
Consensus Handoff Packet
Improve Shipwright's A/B consensus queue metadata handoff for Onboarding Flow Experiment; do not edit the target app source or report HTML renderer.
Metric
- Activation clarity: a new user can identify the first experiment, judge review, and publish path.
Runtime Proof
- Onboarding Flow Experiment has no rendered runtime evidence for its expected signals.
Target Metadata
- Run state: blocked; dogfood blocked; visual missing; promotion needs_more_signal.
- Operator metric: Activation clarity: a new user can identify the first experiment, judge review, and publish path.
- Consensus: Variant A; 3 majority / 1 dissent; score delta +1.2.
- Current blocker: Rendered runtime missing: Onboarding Flow Experiment has no rendered runtime evidence for its expected signals.
- Next action: Start Onboarding Flow Experiment with its configured command or set SHIPWRIGHT_TARGET_ONBOARDING_FLOW_URL to a rendered URL, then rerun runtime inspection.
- Verification: node dist/cli.js target-runtimes --registry shipwright.targets.json
Operator Trust
- Run state: blocked; dogfood blocked; visual missing; promotion needs_more_signal.
Source Boundary
- .shipwright/targets/onboarding-flow is dogfood evidence only; durable changes for this work order belong in Shipwright files.
First Edit
- Start in src/ab-consensus-queue.ts and src/ab-consensus-queue.test.ts; avoid src/report.ts renderer changes in bounded target workers.
Worker Edit Recipe
- Real command 1: run the required rg command from the execution prompt.
- Real command 2: inspect one focused src/ab-consensus-queue.ts range, 160 lines or less.
- Real command 3: edit src/ab-consensus-queue.ts with node --input-type=module -e or perl -0pi; do not edit tests, src/report.ts, run another inspection, or apply_patch.
- After the first edit: do not edit tests; Shipwright CI will run full verification after the worker exits.
- Change shape: make the Onboarding Flow Experiment queue metadata, blocker evidence, next action, or verification command narrower and easier for the next worker to execute.
- Verify with npm run build only before finishing; Shipwright CI runs full verification after the worker exits.
Verify Next
- node dist/cli.js target-runtimes --registry shipwright.targets.json
Experiment Packet
Allocation
- Variant A: 50% - Guided checklist
- Variant B: 50% - Autonomous summary
Events
- shipwright_ab_test_exposed
- shipwright_ab_test_primary_signal
- shipwright_ab_test_guardrail_signal
- shipwright_ab_test_decision
Missing Signals
- accepted decision threshold
- captured visual evidence
Proof
- Gate passed: Judge Matrix
- Gate needs work: Decision: watch
- Gate needs work: Promotion: watch
- Gate needs work: Visual: fail
- Onboarding Flow Experiment has no rendered runtime evidence for its expected signals.
Acceptance
- Complete the primary unblock action for Onboarding Flow Experiment: Start Onboarding Flow Experiment with its configured command or set SHIPWRIGHT_TARGET_ONBOARDING_FLOW_URL to a rendered URL, then rerun runtime inspection.
- Regenerate the report and confirm the item leaves blocked status or records a narrower blocker.
Failed Gates
- Decision: watch
- Promotion: watch
- Visual: fail
Verify
- node dist/cli.js target-runtimes --registry shipwright.targets.json
- npm run check
- node dist/cli.js capture-surfaces --registry shipwright.targets.json --site-dir site --output metrics/surface-captures.json
Clear blocker: Pricing Page Experiment
Pricing Page Experiment is 40% ready; clear the failing gate before assigning Variant B.
Consensus Handoff Packet
Improve Shipwright's A/B consensus queue metadata handoff for Pricing Page Experiment; do not edit the target app source or report HTML renderer.
Metric
- Buyer confidence: a visitor can connect price to shipped A/B outcomes and judge evidence.
Runtime Proof
- Pricing Page Experiment has no rendered runtime evidence for its expected signals.
Target Metadata
- Run state: blocked; dogfood blocked; visual missing; promotion needs_more_signal.
- Operator metric: Buyer confidence — Variant B's price clarity still needs more signal, margin 0.9 below the 1-point threshold; keep the captured Pricing Page surface that shows Variant B's published price beside the scorecard of shipped A/B outcomes so visitors can see precisely how the price maps to the delivered evidence and verify the pricing clarity claim.
- Consensus: Variant B (Judge-proof pricing); 3 majority / 1 dissent; score delta +0.9 (margin 0.9 below the 1-point Buyer confidence threshold; keep the captured Pricing Page surface that shows Variant B's published price beside the scorecard of shipped A/B outcomes so visitors can see precisely how the price maps to the delivered evidence and verify the pricing clarity claim).
- Current blocker: Rendered runtime missing: Pricing Page Experiment has no rendered runtime evidence for its expected signals.
- Next action: Run the Pricing Page Experiment as an A/B subject on Variant B (Judge-proof pricing); keep the captured Pricing Page surface that shows Variant B's published price beside the scorecard of shipped A/B outcomes so visitors can see how the price maps to the delivered evidence.
- Verification: node dist/cli.js target-runtimes --registry shipwright.targets.json
Operator Trust
- Run state: blocked; dogfood blocked; visual missing; promotion needs_more_signal.
Source Boundary
- .shipwright/targets/pricing-page is dogfood evidence only; durable changes for this work order belong in Shipwright files.
First Edit
- Start in src/ab-consensus-queue.ts and src/ab-consensus-queue.test.ts; avoid src/report.ts renderer changes in bounded target workers.
Worker Edit Recipe
- Real command 1: run the required rg command from the execution prompt.
- Real command 2: inspect one focused src/ab-consensus-queue.ts range, 160 lines or less.
- Real command 3: edit src/ab-consensus-queue.ts with node --input-type=module -e or perl -0pi; do not edit tests, src/report.ts, run another inspection, or apply_patch.
- After the first edit: do not edit tests; Shipwright CI will run full verification after the worker exits.
- Change shape: make the Pricing Page Experiment queue metadata, blocker evidence, next action, or verification command narrower and easier for the next worker to execute.
- Verify with npm run build only before finishing; Shipwright CI runs full verification after the worker exits.
Verify Next
- node dist/cli.js target-runtimes --registry shipwright.targets.json
Experiment Packet
Allocation
- Variant A: 50% - Simple plan comparison
- Variant B: 50% - Judge-proof pricing
Events
- shipwright_ab_test_exposed
- shipwright_ab_test_primary_signal
- shipwright_ab_test_guardrail_signal
- shipwright_ab_test_decision
Missing Signals
- accepted decision threshold
- captured visual evidence
Proof
- Gate passed: Judge Matrix
- Gate needs work: Decision: watch
- Gate needs work: Promotion: watch
- Gate needs work: Visual: fail
- Pricing Page Experiment has no rendered runtime evidence for its expected signals.
Acceptance
- Complete the primary unblock action for Pricing Page Experiment: Start Pricing Page Experiment with its configured command or set SHIPWRIGHT_TARGET_PRICING_PAGE_URL to a rendered URL, then rerun runtime inspection.
- Regenerate the report and confirm the item leaves blocked status or records a narrower blocker.
Failed Gates
- Decision: watch
- Promotion: watch
- Visual: fail
Verify
- node dist/cli.js target-runtimes --registry shipwright.targets.json
- npm run check
- node dist/cli.js capture-surfaces --registry shipwright.targets.json --site-dir site --output metrics/surface-captures.json
Shipwright Site
Shipwright Site is the first A/B consensus blocker; clear the evidence gaps before promoting Variant A.
Recommended Next
- Run surface capture after the target runtime renders all expected signals.
- Screenshot evidence missing: Shipwright A/B Lab rendered evidence is not backed by a captured screenshot yet.
- shipwright-site-visual-evidence: Shipwright Site does not have captured visual evidence for this A/B decision. Run `shipwright capture-surfaces` after report generation and publish site/surface-captures.json with a captured screenshot.
- Render a first-class Variant A / Variant B toggle on the website.
Verify
- node dist/cli.js capture-surfaces --registry shipwright.targets.json --site-dir site --output metrics/surface-captures.json
- npm run check
- npm run verify:intake
- curl -fsSL https://shipwright-seven-murex.vercel.app/ab-tests.json
Clear First
Shipwright Site
Time-to-action: can a returning operator identify the next useful Shipwright move?
A/B variant comparison
- Winning
- Experiment cockpit (9.1)
- Runner-up
- Fast winner board (6.7)
- Votes
- A:3 / B:1
- Why
- Lead with a toggleable A/B workspace: Variant A, Variant B, Playwright evidence, model-judge scorecards, and human vote state.
- Risk
- Can hide dissent and weak evidence behind a premature recommendation.
Experiment Packet
Allocation
- Variant A: 50% - Experiment cockpit
- Variant B: 50% - Fast winner board
Events
- shipwright_ab_test_exposed
- shipwright_ab_test_primary_signal
- shipwright_ab_test_guardrail_signal
- shipwright_ab_test_decision
Missing Signals
- accepted decision threshold
- captured visual evidence
Gates
- Decision needs more signal with low confidence and +2.4 margin.
- Promotion needs more signal
- Visual No surface capture manifest entry exists for this subject.
- Dogfood Shipwright A/B Lab is blocked.
- Judge Matrix 3/4 judges aligned with 1 dissent.
Blockers
- Screenshot evidence missing: Shipwright A/B Lab rendered evidence is not backed by a captured screenshot yet.
- shipwright-site-visual-evidence: Shipwright Site does not have captured visual evidence for this A/B decision. Run `shipwright capture-surfaces` after report generation and publish site/surface-captures.json with a captured screenshot.
Next
- Run surface capture after the target runtime renders all expected signals.
- Screenshot evidence missing: Shipwright A/B Lab rendered evidence is not backed by a captured screenshot yet.
- shipwright-site-visual-evidence: Shipwright Site does not have captured visual evidence for this A/B decision. Run `shipwright capture-surfaces` after report generation and publish site/surface-captures.json with a captured screenshot.
- Render a first-class Variant A / Variant B toggle on the website.
Criteria
- Experiment Fit: 9/6 (+3)
- Judgeability: 8/7 (+1)
- Implementation Fit: 9/6 (+3)
- Evidence Quality: 9/5 (+4)
Verify
- node dist/cli.js capture-surfaces --registry shipwright.targets.json --site-dir site --output metrics/surface-captures.json
- npm run check
- npm run verify:intake
- curl -fsSL https://shipwright-seven-murex.vercel.app/ab-tests.json
Onboarding Flow Experiment
Activation clarity: a new user can identify the first experiment, judge review, and publish path.
A/B variant comparison
- Winning
- Guided checklist (8.6)
- Runner-up
- Autonomous summary (7.4)
- Votes
- A:3 / B:1
- Why
- Lead onboarding with a concrete sequence of setup, first experiment, judge review, and publish steps.
- Risk
- Can hide important setup gaps if the summary is too confident.
Experiment Packet
Allocation
- Variant A: 50% - Guided checklist
- Variant B: 50% - Autonomous summary
Events
- shipwright_ab_test_exposed
- shipwright_ab_test_primary_signal
- shipwright_ab_test_guardrail_signal
- shipwright_ab_test_decision
Missing Signals
- accepted decision threshold
- captured visual evidence
Gates
- Decision needs more signal with low confidence and +1.2 margin.
- Promotion needs more signal
- Visual No surface capture manifest entry exists for this subject.
- Dogfood Onboarding Flow Experiment is blocked.
- Judge Matrix 3/4 judges aligned with 1 dissent.
Blockers
- Rendered runtime missing: Onboarding Flow Experiment has no rendered runtime evidence for its expected signals.
- onboarding-flow-visual-evidence: Onboarding Flow Experiment does not have captured visual evidence for this A/B decision. Run `shipwright capture-surfaces` after report generation and publish site/surface-captures.json with a captured screenshot.
Next
- Start Onboarding Flow Experiment with its configured command or set SHIPWRIGHT_TARGET_ONBOARDING_FLOW_URL to a rendered URL, then rerun runtime inspection.
- Rendered runtime missing: Onboarding Flow Experiment has no rendered runtime evidence for its expected signals.
- onboarding-flow-visual-evidence: Onboarding Flow Experiment does not have captured visual evidence for this A/B decision. Run `shipwright capture-surfaces` after report generation and publish site/surface-captures.json with a captured screenshot.
- Shipwright should run Onboarding Flow Experiment as an A/B subject with Variant A: Guided checklist.
Criteria
- Experiment Fit: 9/8 (+1)
- Judgeability: 8/7 (+1)
- Implementation Fit: 9/7 (+2)
- Evidence Quality: 8/7 (+1)
Verify
- node dist/cli.js target-runtimes --registry shipwright.targets.json
- npm run check
- node dist/cli.js capture-surfaces --registry shipwright.targets.json --site-dir site --output metrics/surface-captures.json
- npm run verify:intake
Pricing Page Experiment
Buyer confidence: a visitor can connect price to shipped A/B outcomes and judge evidence.
A/B variant comparison
- Winning
- Judge-proof pricing (8.9)
- Runner-up
- Simple plan comparison (8)
- Votes
- A:1 / B:3
- Why
- Lead pricing with proof: experiments run, judges consulted, human votes collected, and winners shipped.
- Risk
- Underplays the differentiator: autonomous evidence-backed shipping.
Experiment Packet
Allocation
- Variant A: 50% - Simple plan comparison
- Variant B: 50% - Judge-proof pricing
Events
- shipwright_ab_test_exposed
- shipwright_ab_test_primary_signal
- shipwright_ab_test_guardrail_signal
- shipwright_ab_test_decision
Missing Signals
- accepted decision threshold
- captured visual evidence
Gates
- Decision needs more signal with low confidence and +0.9 margin.
- Promotion needs more signal
- Visual No surface capture manifest entry exists for this subject.
- Dogfood Pricing Page Experiment is blocked.
- Judge Matrix 3/4 judges aligned with 1 dissent.
Blockers
- Rendered runtime missing: Pricing Page Experiment has no rendered runtime evidence for its expected signals.
- pricing-page-visual-evidence: Pricing Page Experiment does not have captured visual evidence for this A/B decision. Run `shipwright capture-surfaces` after report generation and publish site/surface-captures.json with a captured screenshot.
Next
- Start Pricing Page Experiment with its configured command or set SHIPWRIGHT_TARGET_PRICING_PAGE_URL to a rendered URL, then rerun runtime inspection.
- Rendered runtime missing: Pricing Page Experiment has no rendered runtime evidence for its expected signals.
- pricing-page-visual-evidence: Pricing Page Experiment does not have captured visual evidence for this A/B decision. Run `shipwright capture-surfaces` after report generation and publish site/surface-captures.json with a captured screenshot.
- Shipwright should run Pricing Page Experiment as an A/B subject with Variant B: Judge-proof pricing.
Criteria
- Experiment Fit: 9/8 (+1)
- Judgeability: 9/8 (+1)
- Implementation Fit: 8/9 (-1)
- Evidence Quality: 9/7 (+2)
Verify
- node dist/cli.js target-runtimes --registry shipwright.targets.json
- npm run check
- node dist/cli.js capture-surfaces --registry shipwright.targets.json --site-dir site --output metrics/surface-captures.json
- npm run verify:intake
Ready To Ship
No items in this lane.
Watch
No items in this lane.
Queue Next Actions
- Run surface capture after the target runtime renders all expected signals.
- Screenshot evidence missing: Shipwright A/B Lab rendered evidence is not backed by a captured screenshot yet.
- shipwright-site-visual-evidence: Shipwright Site does not have captured visual evidence for this A/B decision. Run `shipwright capture-surfaces` after report generation and publish site/surface-captures.json with a captured screenshot.
- Render a first-class Variant A / Variant B toggle on the website.
- Keep model judges, human votes, and Playwright evidence in the same decision packet.
- Generate worker prompts from the winning variant only after evidence gates pass.
Shipwright Site
Should Shipwright lead with a toggleable experiment cockpit or a fast winner board?
Primary metricTime-to-action: can a returning operator identify the next useful Shipwright move?
Score9.1 / 6.7
VotesVariant A: 3, Variant B: 1
Playwright evidencemissing / 0
Decision Rule
- Variant A clears the A/B threshold by 2.4 weighted points. Hold promotion because visual evidence is missing. The A/B decision can be discussed, but promotion needs a rendered screenshot before build work starts.
- Threshold 1.5; margin 2.4; status needs more signal.
- Synthetic product, design, engineering, and operations judges until live traffic exists.
Experiment Packet
- Assignment: synthetic judge
- Readout: needs more signal / low
- shipwright-site selects Variant A with low confidence; 1 observed signal and 2 missing signals.
- Hold Variant A until missing signals are resolved.
Allocation
- Variant A: 50% - Experiment cockpit
- Variant B: 50% - Fast winner board
Event Contract
shipwright_ab_test_exposedshipwright_ab_test_primary_signalshipwright_ab_test_guardrail_signalshipwright_ab_test_decision
Observed Signals
- surface capture missing
Missing Signals
- accepted decision threshold
- captured visual evidence
Playwright Evidence
- No surface capture manifest entry exists for this subject.
- The A/B decision can be discussed, but promotion needs a rendered screenshot before build work starts.
- surface capture missing
Guardrails
- First-time comprehension of what Shipwright is becoming.
- Auditability of the decision through JSON artifacts.
- Visibility of dissent and next actions.
Variant A: Experiment cockpit
Lead with a toggleable A/B workspace: Variant A, Variant B, Playwright evidence, model-judge scorecards, and human vote state.
Audience: Returning operators and agents reviewing autonomous runs.
Experience: Evidence-first console with status, changelog, consensus, and next actions.
Signal: More readers can explain the selected lane and next action without opening logs.
Variant B: Fast winner board
Lead with the winning variant, summarized rationale, and one next action before showing the deeper judge evidence.
Audience: First-time readers trying to understand the product story.
Experience: Narrative journal-led page centered on the latest run.
Signal: More readers understand the story, but fewer can act on the current state.
Next Actions
- Render a first-class Variant A / Variant B toggle on the website.
- Keep model judges, human votes, and Playwright evidence in the same decision packet.
- Generate worker prompts from the winning variant only after evidence gates pass.
Promotion Packet
- Owner: Shipwright website worker
- Rollout: Keep the generated site deterministic; publish Variant A as the default until live traffic exists.
- Sample: Synthetic consensus with multiple LLM judges, a human panel, and visual evidence status: missing.
- Ship: Variant A clears the A/B threshold by 2.4 weighted points. Ship when the generated site exposes the A/B toggle, LLM judges, human votes, and Playwright evidence together.
- Stop: Stop promotion if the first viewport hides current run state, if JSON artifacts stop being generated, or if the page regresses into raw journal text.
Implementation Brief
- Promote Variant A: Experiment cockpit as the default website layout.
- Keep the changelog as product history and the journal as compact audit evidence.
- Preserve dissent in the page so the fast-winner-board risk stays visible.
- Make the A/B consensus artifact good enough for another worker to implement without reading source code.
Instrumentation
- shipwright_ab_test_exposed: A user or dogfood worker sees either variant.
- shipwright_ab_test_primary_signal: The primary metric can be evaluated for the viewed variant.
- shipwright_ab_test_decision: Variant A is promoted, rejected, or sent back for more signal.
Evidence Gaps
- shipwright-site-visual-evidence (blocking): Shipwright Site does not have captured visual evidence for this A/B decision. Run `shipwright capture-surfaces` after report generation and publish site/surface-captures.json with a captured screenshot.
- landing-live-behavior (follow up): The winner is based on offline consensus, not live visitor behavior. Add lightweight page events once Shipwright has real recurring users.
- landing-first-impression (follow up): Design dissent says the product story still needs to survive the evidence-first layout. Compare first-viewport comprehension after each generated site change.
Verify
npm run checknode dist/cli.js capture-surfaces --registry shipwright.targets.json --site-dir site --output metrics/surface-captures.jsonnpm run verify:intakecurl -fsSL https://shipwright-seven-murex.vercel.app/ab-tests.json
Worker Prompt
Use site/ab-tests.json as the source of truth. Improve the Shipwright website by implementing the winning A/B consensus direction while preserving product history, dissent, and machine-readable artifacts.
Onboarding Flow Experiment
Should onboarding lead with a guided checklist or an autonomous summary?
Primary metricActivation clarity: a new user can identify the first experiment, judge review, and publish path.
Score8.6 / 7.4
VotesVariant A: 3, Variant B: 1
Playwright evidencemissing / 0
Decision Rule
- Variant A clears the A/B threshold by 1.2 weighted points. Hold promotion because visual evidence is missing. The A/B decision can be discussed, but promotion needs a rendered screenshot before build work starts.
- Threshold 1; margin 1.2; status needs more signal.
- Synthetic app-specific judges derived from the target consensus rubric.
Experiment Packet
- Assignment: experiment subject
- Readout: needs more signal / low
- onboarding-flow selects Variant A with low confidence; 1 observed signal and 2 missing signals.
- Hold Variant A until missing signals are resolved.
Allocation
- Variant A: 50% - Guided checklist
- Variant B: 50% - Autonomous summary
Event Contract
shipwright_ab_test_exposedshipwright_ab_test_primary_signalshipwright_ab_test_guardrail_signalshipwright_ab_test_decision
Observed Signals
- surface capture missing
Missing Signals
- accepted decision threshold
- captured visual evidence
Playwright Evidence
- No surface capture manifest entry exists for this subject.
- The A/B decision can be discussed, but promotion needs a rendered screenshot before build work starts.
- surface capture missing
Guardrails
- The winning direction preserves the target app's declared primary job.
- The losing direction's strongest risk remains visible before implementation.
- Future dogfood runs have concrete UI signals to inspect.
Variant A: Guided checklist
Lead onboarding with a concrete sequence of setup, first experiment, judge review, and publish steps.
Audience: New operators setting up their first autonomous A/B run.
Experience: Guided checklist for setup, first experiment, judge review, and publish steps.
Signal: New users can complete the first run without reading docs or raw logs.
Variant B: Autonomous summary
Lead onboarding with what Shipwright already inferred and one high-confidence next action.
Audience: Returning operators who want Shipwright to infer the next step.
Experience: Autonomous summary that explains inferred state and recommends one action.
Signal: Operators move faster when setup assumptions are already correct.
Next Actions
- Shipwright should run Onboarding Flow Experiment as an A/B subject with Variant A: Guided checklist.
Promotion Packet
- Owner: Onboarding Flow Experiment experiment worker
- Rollout: Build as a generated UI variant first, then promote the winner after judge and human-vote evidence stays coherent.
- Sample: Synthetic experiment judges plus visual evidence status: missing.
- Ship: Variant A clears the A/B threshold by 1.2 weighted points. Ship when the subject has captured Playwright evidence and no blocking evidence gaps remain.
- Stop: Stop promotion if the screenshots are missing, the judge matrix loses consensus, or the losing variant's primary risk becomes a real blocker.
Implementation Brief
- Promote Variant A: Guided checklist for Onboarding Flow Experiment.
- Shipwright should run Onboarding Flow Experiment as an A/B subject with Variant A: Guided checklist.
- Primary target job: Built-in onboarding UI variant.
- Keep the losing variant's strongest risk visible in the implementation notes.
Instrumentation
- shipwright_ab_test_exposed: A user or dogfood worker sees either variant.
- shipwright_ab_test_primary_signal: The primary metric can be evaluated for the viewed variant.
- shipwright_ab_test_decision: Variant A is promoted, rejected, or sent back for more signal.
Evidence Gaps
- onboarding-flow-visual-evidence (blocking): Onboarding Flow Experiment does not have captured visual evidence for this A/B decision. Run `shipwright capture-surfaces` after report generation and publish site/surface-captures.json with a captured screenshot.
- onboarding-flow-live-behavior (follow up): The current decision is an offline consensus, not a live product experiment. Capture real usage events after the first UI slice ships.
Verify
npm run checknode dist/cli.js capture-surfaces --registry shipwright.targets.json --site-dir site --output metrics/surface-captures.jsonnpm run verify:intake
Worker Prompt
Use site/ab-tests.json, site/consensus-matrix.json, and site/surface-captures.json to implement Variant A for Onboarding Flow Experiment. Preserve the primary job "Built-in onboarding UI variant" and verify the generated screenshots before shipping.
Pricing Page Experiment
Should pricing lead with a simple plan comparison or proof from judge outcomes?
Primary metricBuyer confidence: a visitor can connect price to shipped A/B outcomes and judge evidence.
Score8.9 / 8
VotesVariant A: 1, Variant B: 3
Playwright evidencemissing / 0
Decision Rule
- The margin is 0.9, below the 1 point threshold, so more signal is required. Hold promotion because visual evidence is missing. The A/B decision can be discussed, but promotion needs a rendered screenshot before build work starts.
- Threshold 1; margin 0.9; status needs more signal.
- Synthetic app-specific judges derived from the target consensus rubric.
Experiment Packet
- Assignment: experiment subject
- Readout: needs more signal / low
- pricing-page selects Variant B with low confidence; 1 observed signal and 2 missing signals.
- Hold Variant B until missing signals are resolved.
Allocation
- Variant A: 50% - Simple plan comparison
- Variant B: 50% - Judge-proof pricing
Event Contract
shipwright_ab_test_exposedshipwright_ab_test_primary_signalshipwright_ab_test_guardrail_signalshipwright_ab_test_decision
Observed Signals
- surface capture missing
Missing Signals
- accepted decision threshold
- captured visual evidence
Playwright Evidence
- No surface capture manifest entry exists for this subject.
- The A/B decision can be discussed, but promotion needs a rendered screenshot before build work starts.
- surface capture missing
Guardrails
- The winning direction preserves the target app's declared primary job.
- The losing direction's strongest risk remains visible before implementation.
- Future dogfood runs have concrete UI signals to inspect.
Variant A: Simple plan comparison
Lead pricing with straightforward plans, limits, and the first practical upgrade point.
Audience: Buyers scanning pricing before they understand the platform deeply.
Experience: Simple plan comparison with limits, usage, and the first upgrade moment.
Signal: Visitors understand cost and constraints quickly.
Variant B: Judge-proof pricing
Lead pricing with proof: experiments run, judges consulted, human votes collected, and winners shipped.
Audience: Buyers evaluating whether autonomous experimentation is worth paying for.
Experience: Outcome proof cards showing experiments run, judges consulted, votes collected, and winners shipped.
Signal: Visitors connect pricing to evidence-backed shipping outcomes.
Next Actions
- Shipwright should run Pricing Page Experiment as an A/B subject with Variant B: Judge-proof pricing.
Promotion Packet
- Owner: Pricing Page Experiment experiment worker
- Rollout: Build as a generated UI variant first, then promote the winner after judge and human-vote evidence stays coherent.
- Sample: Synthetic experiment judges plus visual evidence status: missing.
- Ship: The margin is 0.9, below the 1 point threshold, so more signal is required. Ship when the subject has captured Playwright evidence and no blocking evidence gaps remain.
- Stop: Stop promotion if the screenshots are missing, the judge matrix loses consensus, or the losing variant's primary risk becomes a real blocker.
Implementation Brief
- Promote Variant B: Judge-proof pricing for Pricing Page Experiment.
- Shipwright should run Pricing Page Experiment as an A/B subject with Variant B: Judge-proof pricing.
- Primary target job: Built-in pricing UI variant.
- Keep the losing variant's strongest risk visible in the implementation notes.
Instrumentation
- shipwright_ab_test_exposed: A user or dogfood worker sees either variant.
- shipwright_ab_test_primary_signal: The primary metric can be evaluated for the viewed variant.
- shipwright_ab_test_decision: Variant B is promoted, rejected, or sent back for more signal.
Evidence Gaps
- pricing-page-visual-evidence (blocking): Pricing Page Experiment does not have captured visual evidence for this A/B decision. Run `shipwright capture-surfaces` after report generation and publish site/surface-captures.json with a captured screenshot.
- pricing-page-live-behavior (follow up): The current decision is an offline consensus, not a live product experiment. Capture real usage events after the first UI slice ships.
Verify
npm run checknode dist/cli.js capture-surfaces --registry shipwright.targets.json --site-dir site --output metrics/surface-captures.jsonnpm run verify:intake
Worker Prompt
Use site/ab-tests.json, site/consensus-matrix.json, and site/surface-captures.json to implement Variant B for Pricing Page Experiment. Preserve the primary job "Built-in pricing UI variant" and verify the generated screenshots before shipping.
Dogfood Status Build-time readiness captured across the built-in experiment subjects.
0/3 experiment subjects are ready; 3 blocked; 0 need watch.
Single dogfood view derived from target inspection, credentials, runtime starts, rendered probes, surface captures, and consensus handoffs.
Shipwright A/B Lab
Shipwright A/B Lab is blocked by 2 evidence gaps.
- Target
- remote
- Credential
- not_required
- Runtime start
- not_recorded
- Plan
- self
Blocker Diagnosis
Screenshot evidence missing: Shipwright A/B Lab rendered evidence is not backed by a captured screenshot yet.
- Next
- Run surface capture after the target runtime renders all expected signals.
- Verify
node dist/cli.js capture-surfaces --registry shipwright.targets.json --site-dir site --output metrics/surface-captures.json
Blockers
- Surface capture evidence is missing.
- shipwright-site-visual-evidence: Shipwright Site does not have captured visual evidence for this A/B decision. Run `shipwright capture-surfaces` after report generation and publish site/surface-captures.json with a captured screenshot.
Next
- Run surface capture after the target runtime renders all expected signals.
- Surface capture evidence is missing.
- shipwright-site-visual-evidence: Shipwright Site does not have captured visual evidence for this A/B decision. Run `shipwright capture-surfaces` after report generation and publish site/surface-captures.json with a captured screenshot.
- Keep this subject in the default experiment path.
Evidence
- Shipwright A/B Lab rendered evidence is not backed by a captured screenshot yet.
- remote url configured: https://shipwright-seven-murex.vercel.app
- No repository credential is required for this target.
- Fetched https://shipwright-seven-murex.vercel.app; matched 3/3 expected runtime signals.
Onboarding Flow Experiment
Onboarding Flow Experiment is blocked by 3 evidence gaps.
- Target
- metadata_only
- Credential
- not_required
- Runtime start
- not_recorded
- Plan
- self
Blocker Diagnosis
Rendered runtime missing: Onboarding Flow Experiment has no rendered runtime evidence for its expected signals.
- Next
- Start Onboarding Flow Experiment with its configured command or set SHIPWRIGHT_TARGET_ONBOARDING_FLOW_URL to a rendered URL, then rerun runtime inspection.
- Verify
node dist/cli.js target-runtimes --registry shipwright.targets.json
Blockers
- Onboarding Flow Experiment: runtime not_configured
- Surface capture evidence is missing.
- onboarding-flow-visual-evidence: Onboarding Flow Experiment does not have captured visual evidence for this A/B decision. Run `shipwright capture-surfaces` after report generation and publish site/surface-captures.json with a captured screenshot.
Next
- Start Onboarding Flow Experiment with its configured command or set SHIPWRIGHT_TARGET_ONBOARDING_FLOW_URL to a rendered URL, then rerun runtime inspection.
- Onboarding Flow Experiment: runtime not_configured
- Surface capture evidence is missing.
- onboarding-flow-visual-evidence: Onboarding Flow Experiment does not have captured visual evidence for this A/B decision. Run `shipwright capture-surfaces` after report generation and publish site/surface-captures.json with a captured screenshot.
Evidence
- Onboarding Flow Experiment has no rendered runtime evidence for its expected signals.
- target is generated by this repository
- No repository credential is required for this target.
- No runtime URL is configured for rendered dogfood.
Pricing Page Experiment
Pricing Page Experiment is blocked by 3 evidence gaps.
- Target
- metadata_only
- Credential
- not_required
- Runtime start
- not_recorded
- Plan
- self
Blocker Diagnosis
Rendered runtime missing: Pricing Page Experiment has no rendered runtime evidence for its expected signals.
- Next
- Start Pricing Page Experiment with its configured command or set SHIPWRIGHT_TARGET_PRICING_PAGE_URL to a rendered URL, then rerun runtime inspection.
- Verify
node dist/cli.js target-runtimes --registry shipwright.targets.json
Blockers
- Pricing Page Experiment: runtime not_configured
- Surface capture evidence is missing.
- pricing-page-visual-evidence: Pricing Page Experiment does not have captured visual evidence for this A/B decision. Run `shipwright capture-surfaces` after report generation and publish site/surface-captures.json with a captured screenshot.
Next
- Start Pricing Page Experiment with its configured command or set SHIPWRIGHT_TARGET_PRICING_PAGE_URL to a rendered URL, then rerun runtime inspection.
- Pricing Page Experiment: runtime not_configured
- Surface capture evidence is missing.
- pricing-page-visual-evidence: Pricing Page Experiment does not have captured visual evidence for this A/B decision. Run `shipwright capture-surfaces` after report generation and publish site/surface-captures.json with a captured screenshot.
Evidence
- Pricing Page Experiment has no rendered runtime evidence for its expected signals.
- target is generated by this repository
- No repository credential is required for this target.
- No runtime URL is configured for rendered dogfood.
Experiment Next Actions
- Run surface capture after the target runtime renders all expected signals.
- Surface capture evidence is missing.
- shipwright-site-visual-evidence: Shipwright Site does not have captured visual evidence for this A/B decision. Run `shipwright capture-surfaces` after report generation and publish site/surface-captures.json with a captured screenshot.
- Keep this subject in the default experiment path.
- Use this rendered runtime as the baseline for the next UI consensus comparison.
- Render a first-class Variant A / Variant B toggle on the website.
Consensus Board Recorded promotion lanes and worker prompts for an implementation pass.
0/3 UI consensus subjects are ready for build; 3 need more signal.
A/B consensus board for deciding what a worker can implement now versus what needs runtime, credential, or screenshot evidence first.
Ready For Build
Consensus winners with accepted decision rules and captured visual evidence.
No subjects in this lane.
Needs More Signal
Consensus winners blocked by missing screenshots, runtime evidence, or credential setup.
Shipwright Site
Time-to-action: can a returning operator identify the next useful Shipwright move?
Blockers
- shipwright-site-visual-evidence: Shipwright Site does not have captured visual evidence for this A/B decision. Run `shipwright capture-surfaces` after report generation and publish site/surface-captures.json with a captured screenshot.
Next
- Render a first-class Variant A / Variant B toggle on the website.
- Keep model judges, human votes, and Playwright evidence in the same decision packet.
- Generate worker prompts from the winning variant only after evidence gates pass.
Verify
- npm run check
- node dist/cli.js capture-surfaces --registry shipwright.targets.json --site-dir site --output metrics/surface-captures.json
- npm run verify:intake
Onboarding Flow Experiment
Activation clarity: a new user can identify the first experiment, judge review, and publish path.
Blockers
- onboarding-flow-visual-evidence: Onboarding Flow Experiment does not have captured visual evidence for this A/B decision. Run `shipwright capture-surfaces` after report generation and publish site/surface-captures.json with a captured screenshot.
Next
- Shipwright should run Onboarding Flow Experiment as an A/B subject with Variant A: Guided checklist.
- onboarding-flow-visual-evidence: Onboarding Flow Experiment does not have captured visual evidence for this A/B decision. Run `shipwright capture-surfaces` after report generation and publish site/surface-captures.json with a captured screenshot.
- onboarding-flow-live-behavior: Capture real usage events after the first UI slice ships.
Verify
- npm run check
- node dist/cli.js capture-surfaces --registry shipwright.targets.json --site-dir site --output metrics/surface-captures.json
- npm run verify:intake
Pricing Page Experiment
Buyer confidence: a visitor can connect price to shipped A/B outcomes and judge evidence.
Blockers
- pricing-page-visual-evidence: Pricing Page Experiment does not have captured visual evidence for this A/B decision. Run `shipwright capture-surfaces` after report generation and publish site/surface-captures.json with a captured screenshot.
Next
- Shipwright should run Pricing Page Experiment as an A/B subject with Variant B: Judge-proof pricing.
- pricing-page-visual-evidence: Pricing Page Experiment does not have captured visual evidence for this A/B decision. Run `shipwright capture-surfaces` after report generation and publish site/surface-captures.json with a captured screenshot.
- pricing-page-live-behavior: Capture real usage events after the first UI slice ships.
Verify
- npm run check
- node dist/cli.js capture-surfaces --registry shipwright.targets.json --site-dir site --output metrics/surface-captures.json
- npm run verify:intake
Board Next Actions
- Render a first-class Variant A / Variant B toggle on the website.
- Keep model judges, human votes, and Playwright evidence in the same decision packet.
- Generate worker prompts from the winning variant only after evidence gates pass.
- shipwright-site-visual-evidence: Shipwright Site does not have captured visual evidence for this A/B decision. Run `shipwright capture-surfaces` after report generation and publish site/surface-captures.json with a captured screenshot.
- landing-live-behavior: Add lightweight page events once Shipwright has real recurring users.
- landing-first-impression: Compare first-viewport comprehension after each generated site change.
Codex Worker Autonomous write result, changed files, and failure evidence.
Codex Worker Run
not_recordedNo Codex worker run has been recorded for this report.
No changed files recorded yet.
Evidence
- codex-worker-status.json missing
Next Actions
- Run Shipwright Dogfood in non-dry-run mode to capture worker execution evidence.
Worker Contract Whether the autonomous worker stayed inside the command contract.
Codex Worker Contract
unknownNo Codex worker contract trace has been recorded for this report.
Evidence
- commands: 0
- first edit command index: -1
No command trace captured yet.
Next Actions
- Run Shipwright Dogfood in non-dry-run mode to capture worker contract evidence.
UI Experiments Poll questions, responses, and synthesis outputs.
Shipwright A/B Lab UI Consensus Poll
Autonomous A/B experiment console. Should the experiment console optimize for operator confidence or fast winner selection?
Winner Variant A: Evidence-first surface.
Readiness remote
Surface rendered
Poll Questions
- Should the experiment console optimize for operator confidence or fast winner selection? Use Variant A: Evidence-first surface.
- What should block Shipwright from implementing the winning UI direction? The losing variant may still be better for first-time users or marketing pages.
Responses
- GPT-5.1 Judge selected Variant A at 9/10.
- Claude Sonnet Judge selected Variant A at 8/10.
- Gemini Judge selected Variant B at 7/10.
- Human Panel selected Variant A at 8/10.
Synthesis
- 3/4 judges selected Variant A.
- Shipwright should run Shipwright A/B Lab as an A/B subject with Variant A: Evidence-first surface.
- Use the captured rendered surface signals as the baseline for the next UI comparison.
Surface Signals
- No surface signals captured.
Source Model
- No source model extracted yet.
Onboarding Flow Experiment UI Consensus Poll
Built-in onboarding UI variant. Should onboarding lead with a guided checklist or an autonomous summary?
Winner Variant A: Guided checklist.
Readiness metadata only
Surface metadata only
Poll Questions
- Should onboarding lead with a guided checklist or an autonomous summary? Use Variant A: Guided checklist.
- What should block Shipwright from implementing the winning UI direction? The losing variant may still be better for first-time users or marketing pages.
Responses
- GPT-5.1 Judge selected Variant A at 9/10.
- Claude Sonnet Judge selected Variant A at 8/10.
- Gemini Judge selected Variant B at 7/10.
- Human Panel selected Variant A at 8/10.
Synthesis
- 3/4 judges selected Variant A.
- Shipwright should run Onboarding Flow Experiment as an A/B subject with Variant A: Guided checklist.
- Use declared subject metadata until generated UI evidence is available.
Surface Signals
- npm run check
- npm run report
Source Model
- No source model extracted yet.
Pricing Page Experiment UI Consensus Poll
Built-in pricing UI variant. Should pricing lead with a simple plan comparison or proof from judge outcomes?
Winner Variant B: Judge-proof pricing.
Readiness metadata only
Surface metadata only
Poll Questions
- Should pricing lead with a simple plan comparison or proof from judge outcomes? Use Variant B: Judge-proof pricing.
- What should block Shipwright from implementing the winning UI direction? The losing variant may still be better for operators who need dense controls.
Responses
- GPT-5.1 Judge selected Variant B at 9/10.
- Claude Sonnet Judge selected Variant B at 8/10.
- Gemini Judge selected Variant A at 7/10.
- Human Panel selected Variant B at 8/10.
Synthesis
- 3/4 judges selected Variant B.
- Shipwright should run Pricing Page Experiment as an A/B subject with Variant B: Judge-proof pricing.
- Use declared subject metadata until generated UI evidence is available.
Surface Signals
- npm run check
- npm run report
Source Model
- No source model extracted yet.
UI Surfaces Rendered or source-level surface evidence.
shipwright-site
Title: Shipwright
Headings: none
Signals: none
onboarding-flow
Title: unknown
Headings: none
Signals: npm run check, npm run report
pricing-page
Title: unknown
Headings: none
Signals: npm run check, npm run report
Runtime Evidence Runtime URLs, matched signals, and missing signals.
Shipwright A/B Lab
renderedURL: https://shipwright-seven-murex.vercel.app
Start: npm run report
Matched: 3/3
Matched Signals
- A/B Test Consensus
- LLM Judges
- Variant Toggle
Next Actions
- Use this rendered runtime as the baseline for the next UI consensus comparison.
Onboarding Flow Experiment
not configuredURL: none
Start: none
Matched: 0/3
Missing Signals
- Guided checklist
- Judge review
- Publish path
Next Actions
- Add a runtime URL for Onboarding Flow Experiment so Shipwright can fetch rendered UI evidence.
Pricing Page Experiment
not configuredURL: none
Start: none
Matched: 0/3
Missing Signals
- Judge-proof pricing
- Experiments run
- Winners shipped
Next Actions
- Add a runtime URL for Pricing Page Experiment so Shipwright can fetch rendered UI evidence.
Runtime Start Attempts What Shipwright tried to start for each subject.
No runtime start attempts recorded yet.
Doctor One-command readiness for imported GitHub projects.
Shipwright Doctor
not recordedNo Shipwright doctor status has been recorded for this report.
Workspace: /vercel/path0
Evidence
- metrics/doctor-status.json missing
Next Actions
- Run shipwright doctor before enabling scheduled autonomous runs.
No doctor checks recorded yet.
Adoption Reusable GitHub Actions onboarding and evidence wiring.
GitHub Adoption
not recordedNo Shipwright adoption check has been recorded for this report.
Workflow: missing
Evidence
- metrics/adoption-status.json missing
Next Actions
- Run shipwright ci-run before enabling scheduled writes.
No adoption checks recorded yet.
Project Dependencies Package manager detection and install evidence for imported projects.
Project Dependencies
not recordedNo project dependency install status has been recorded.
Workspace: .
Install: none
Evidence
- metrics/project-dependency-status.json missing
Next Actions
- Run shipwright install-project-dependencies before verification.
No project dependency install steps recorded yet.
Browser Install Playwright browser readiness for surface capture and judge evidence.
Browser Install
not recordedNo Playwright browser install status has been recorded.
Runtime: .
Command: npx playwright install --with-deps chromium
Evidence
- metrics/browser-install-status.json missing
Next Actions
- Run shipwright install-browser before surface capture steps.
Safety YOLO and autonomous mode policy readiness.
Safety Policy
not recordedNo Shipwright safety check has been recorded for this report.
Evidence
- safety-status.json missing
Next Actions
- Run shipwright safety-check before orchestration in GitHub Actions.
No safety checks recorded yet.
Verification Post-worker command gate and durable status evidence.
Verification Gate
not recordedNo verification status has been recorded for this report.
Workspace: /vercel/path0
Evidence
- metrics/verification-status.json missing
Next Actions
- Run shipwright verify after autonomous worker changes to capture verification evidence.
No verification commands recorded yet.
Autonomy Readiness Whether this build snapshot recorded permission to write and push through the autonomous loop.
Autonomy Gate
not recordedNo Shipwright autonomy readiness status has been recorded for this report.
Allowed paths: none
Evidence
- metrics/autonomy-readiness-status.json missing
Next Actions
- Run shipwright ci-work-cycle before enabling autonomous or YOLO writes.
No autonomy readiness checks recorded yet.
Deployment Vercel deploy state and next action.
Vercel Site
deployedProvider: vercel
Blocker: none
URL: https://shipwright-seven-murex.vercel.app
Canonical Vercel production artifact is deployed from e80ed23 on main.
Required Secrets
- VERCEL_TOKEN: missing
- VERCEL_ORG_ID: configured
- VERCEL_PROJECT_ID: configured
Evidence
- provider: vercel
- state: deployed
- blocker: none
- VERCEL_TOKEN: missing
- VERCEL_ORG_ID: configured
- VERCEL_PROJECT_ID: configured
Git Publish Direct-to-main commit and push evidence.
Main Branch Publish
publishedRelease source e80ed23 is published on origin/main and bound to this Vercel production artifact.
Commit: e80ed238331eafc832b280945d9e9190863786d4
No allowed files were published in this run.
Evidence
- commit: e80ed238331eafc832b280945d9e9190863786d4
- identity_source: vercel
- checkout_commit: missing
- remote_ref: missing
- remote_ref_matches: false
- vercel_git_commit: e80ed238331eafc832b280945d9e9190863786d4
Codex Provider OpenRouter provider setup and model readiness.
OpenRouter Codex
skippedModel: openai/gpt-5.1-codex-mini
Config: ~/.codex/config.toml
Env key: OPENROUTER_API_KEY
OPENROUTER_API_KEY is not set; Codex provider setup was skipped.
Evidence
- provider: openrouter
- model: openai/gpt-5.1-codex-mini
- OPENROUTER_API_KEY: missing
Next Actions
- Add OPENROUTER_API_KEY as a GitHub Actions secret before non-dry-run writes.
Experiment Subjects Subject metadata and recommendations captured by this build.
Shipwright A/B Lab
Question: Should the experiment console optimize for operator confidence or fast winner selection?
Winner: Variant A - Evidence-first surface
Shipwright should run Shipwright A/B Lab as an A/B subject with Variant A: Evidence-first surface.
remote
Package: shipwright
Package manager: npm
Lockfile: package-lock.json
Install: npm ci
Framework: static-site
Scripts: vercel deploy
Onboarding Flow Experiment
Question: Should onboarding lead with a guided checklist or an autonomous summary?
Winner: Variant A - Guided checklist
Shipwright should run Onboarding Flow Experiment as an A/B subject with Variant A: Guided checklist.
metadata only
Package: shipwright
Package manager: npm
Lockfile: package-lock.json
Install: npm ci
Framework: static-site
Scripts: none
Pricing Page Experiment
Question: Should pricing lead with a simple plan comparison or proof from judge outcomes?
Winner: Variant B - Judge-proof pricing
Shipwright should run Pricing Page Experiment as an A/B subject with Variant B: Judge-proof pricing.
metadata only
Package: shipwright
Package manager: npm
Lockfile: package-lock.json
Install: npm ci
Framework: static-site
Scripts: none
Experiment Subject Plan Preparation plan for each generated subject.
Shipwright A/B Lab
Repository: https://github.com/matthoffner/shipwright.git
Start: npm run report
Checks: none
Next Actions
- Keep validating the generated website before using it as the baseline for other experiment subjects.
Onboarding Flow Experiment
Repository: https://github.com/matthoffner/shipwright.git
Start: npm run report
Checks: none
Next Actions
- Keep validating the generated website before using it as the baseline for other experiment subjects.
Pricing Page Experiment
Repository: https://github.com/matthoffner/shipwright.git
Start: npm run report
Checks: none
Next Actions
- Keep validating the generated website before using it as the baseline for other experiment subjects.
Target Checkouts Repository and workspace materialization evidence.
No target checkout evidence recorded yet.
Credential Readiness Secret and credential checks for the run.
Shipwright A/B Lab
not requiredSecret: none
Repository: none
Evidence
- No repository credential is required for this target.
Next Actions
- Keep this subject in the default experiment path.
Onboarding Flow Experiment
not requiredSecret: none
Repository: none
Evidence
- No repository credential is required for this target.
Next Actions
- Keep this subject in the default experiment path.
Pricing Page Experiment
not requiredSecret: none
Repository: none
Evidence
- No repository credential is required for this target.
Next Actions
- Keep this subject in the default experiment path.
Product History Changelog-derived product memory.
Evidence-Bound Release Stories
- Added: Proof Story v0 — compiles a human-approved claim set, published commit receipt, deployed HTTPS receipt, and fresh same-origin UI capture into a provider-free 15-second browser story, poster, share copy, release-note draft, and claim-to-evidence manifest.
- Added: Fail-closed release media — rejects unpublished source, unproven deploys, stale or wrong-origin captures, missing claim evidence, credential-shaped story text, and unapproved storyboards before producing publishable artifacts.
Canonical Release Receipts
- Fixed: Terminal public proof — closes the release loop on the canonical production artifact when its commit, repository, project, and URL match, while leaving missing direct-token and remote-tracking evidence visible.
Governed Runtime Product Identity
- Changed: Durable product hierarchy — makes the public surface lead with Shipwright's governed intent-to-merge-or-blocker runtime before showing decision layers, initiatives, and run evidence.
- Changed: Subordinate release framing — keeps Surface Grill and the latest operational release visible without letting either replace Shipwright's durable product mission.
Bounded External Waits
- Fixed: Self-healing schedules — turns stalled browser setup, model judging, and Vercel calls into explicit timeout evidence instead of holding every later run in the queue.
- Fixed: Workflow run ceiling — caps dogfood and reusable jobs at 30 minutes so one unhealthy provider cannot occupy the scheduler indefinitely.
Evidence-Only Watch Runs
- Fixed: No-churn watch work — keeps evidence-only watch decisions in workflow artifacts instead of forcing copy edits, regenerating history, or pushing a source commit.
- Fixed: Canonical release verification — points scheduled runtime checks at the published Surface Grill deployment.
Autonomous Dogfood Runtime
- Added: Add Typed Codex Provider Setup — Add typed codex provider setup.
- Added: Surface Codex Contract Failures — Surface codex contract failures.
- Fixed: Recognize Codex File Change Events — Recognize codex file change events.
- Fixed: Classify Codex Agents Searches — Classify codex agents searches.
- Fixed: Align Codex Guard With Worker Edit Recipe — Align codex guard with worker edit recipe.
Shipwright Product Updates
- Added: Add Variant Judge Runs — Add variant judge runs.
- Added: Pivot Shipwright To A/B Experiment Platform — Pivot shipwright to ab experiment platform.
- Added: Add A/B Consensus Worker Edit Recipes — Add ab consensus worker edit recipes.
- Added: Surface A/B Consensus Execution Metadata — Surface ab consensus execution metadata.
- Added: Add A/B Consensus Handoff Packets — Add ab consensus handoff packets.
Consensus Work Orders
- Added: A/B consensus work orders — turns ready consensus winners and blocker-clearing tasks into assignable worker packets above the detailed lanes.
- Added: A/B consensus priority backlog — ranks consensus work orders with priority, effort, and next verification commands so workers can act from the generated queue.
- Fixed: A/B consensus work orders — turns ready consensus winners and blocker-clearing tasks into assignable worker packets above the detailed lanes.
- Fixed: A/B consensus readiness actions — keeps blocked target summary cards pointed at unblock work instead of promotion handoffs.
Product History Surface
- Fixed: Artifact-only dogfood journals — keeps dogfood journal entries in workflow evidence artifacts so tracked history stays focused on the changelog.
Product History Quality
- Fixed: Changelog history window — keeps the automated changelog scan wide enough to preserve older product outcomes during dogfood refreshes.
Autonomous Deployment Evidence
- Added: Website evidence artifact — uploads the generated site, screenshots, and machine-readable consensus artifacts when Vercel cannot publish the report.
- Added: Deploy status evidence — records Vercel readiness and deploy failures as structured evidence so stale live sites do not look current.
- Fixed: Deploy status evidence — records Vercel readiness and deploy failures as structured evidence so stale live sites do not look current.
Product History Benchmark
- Added: Product history section guard — flags oversized changelog sections so Shipwright keeps copying DevBox's concise outcome history instead of growing giant buckets.
- Fixed: Product history section guard — flags oversized changelog sections so Shipwright keeps copying DevBox's concise outcome history instead of growing giant buckets.
DevBox Changelog Benchmark Checks that keep the product history readable.
6/7 DevBox-style product history checks pass.
Shipwright should keep copying the useful DevBox split: changelog for product history, journal for audit evidence.
- Dated sections name product outcomes.
- Entries are grouped under Added, Changed, and Fixed.
- Bullets use a bold outcome label followed by a short user-facing explanation.
- Source commits remain visible, while routine run journals stay audit-only.
Dated Outcome Sections pass
23 dated product outcome sections are available.
Evidence
- Evidence-Bound Release Stories
- Canonical Release Receipts
- Governed Runtime Product Identity
- Bounded External Waits
Next
- Keep grouping changes by named product outcome instead of dumping every run into one feed.
Added Changed Fixed Grouping pass
3 changelog categories are represented: Added, Fixed, Changed.
Evidence
- Added
- Fixed
- Changed
Next
- Preserve DevBox-style Added, Changed, and Fixed category headings as the product matures.
Concise Product Bullets pass
915/915 entries use the DevBox-style bold outcome plus one-line explanation.
Evidence
- Proof Story v0
- Fail-closed release media
- Terminal public proof
- Durable product hierarchy
Next
- Rewrite vague commit-derived entries into product outcome bullets before publishing.
Source Traceability pass
906/915 entries retain source commit references.
Evidence
- Add Typed Codex Provider Setup: f8681de
- Surface Codex Contract Failures: 14022ba
- Recognize Codex File Change Events: 9bd11f6
- Classify Codex Agents Searches: 3fd8fd5
Next
- Keep source commit links on every generated changelog bullet.
Journal Noise Removed pass
No routine dogfood or journal-only entries are promoted into product history.
Next
- Keep dogfood run bookkeeping in metrics/journal artifacts and reserve CHANGELOG.md for product outcomes.
Named Outcomes pass
Section titles name product outcomes instead of generic update buckets.
Evidence
- Evidence-Bound Release Stories
- Canonical Release Receipts
- Governed Runtime Product Identity
- Bounded External Waits
Next
- Prefer headings like DevBox's V5 onboarding or duplicate-MR guardrail sections over generic update labels.
Focused Section Size fail
Largest changelog section has 225 entries; DevBox-style sections stay small and outcome-specific.
Evidence
- Shipwright Product Updates: 225 entries
- Autonomous Dogfood Runtime: 140 entries
- Consensus Work Orders: 80 entries
- Consensus Experiment Design: 52 entries
Next
- Split oversized sections into narrower dated outcomes before the website treats product history as healthy.
Historical Run Audit A source-bound workflow journal entry; not the live run state.
- Writer
- matthoffner
- Repo
- matthoffner/shipwright
- Mode
- yolo
- Outcome
- would_run
- Lane
- intake
- Task
- intake:advance_runtime
- Run
- https://github.com/matthoffner/shipwright/actions/runs/27900743899
Operating Model How Shipwright decides when to plan, write, or stop.
Dry runs explain the next move before Shipwright writes code.
Autonomous runs turn bounded work into verified changes.
YOLO mode keeps shipping while the changelog carries product history.